Reload or Recompute? A Calibrated Rule for KV-Cache Reuse Across Commodity GPUs
 M Mohith
Summary
When a conversation resumes, a server can reload its saved working state or calculate it again. This study tests a rule for choosing the faster option across L4, A10 and A10G GPUs. The rule uses about a minute of calibration before making its predictions. Extending those predictions to much longer conversations is a known failure case.
Key findings
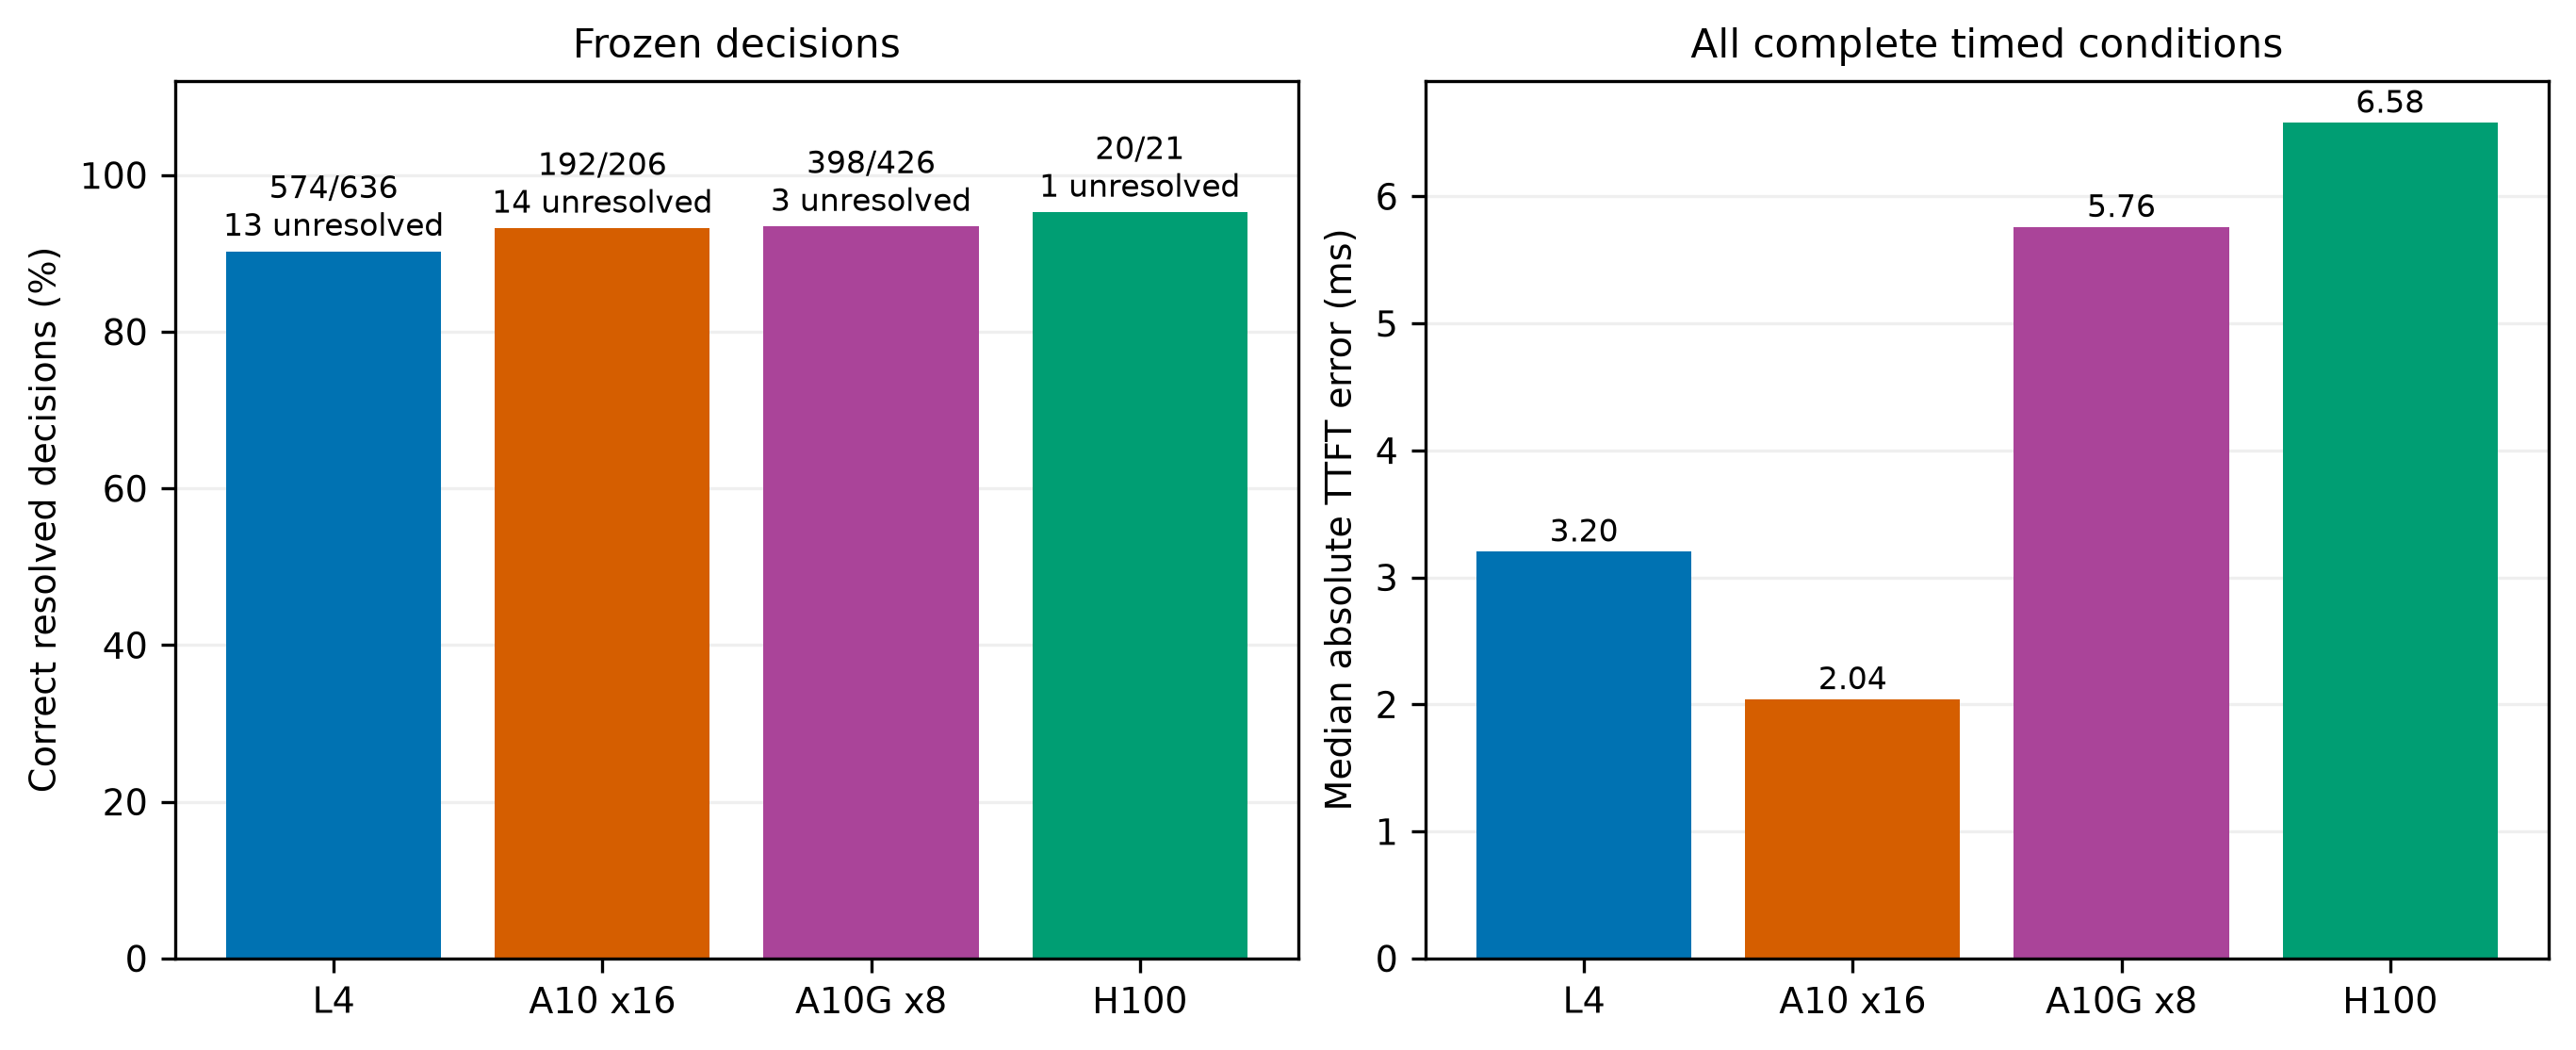
- Frozen predictions from about a minute of calibration correctly classified 574/636 resolved decisions on L4, 192/206 on A10, and 398/426 on A10G.
- Break-even bandwidth rose from 100–400 MB/s on T4 to 800–1,600 MB/s on L4/A10 for Qwen2.5-1.5B with a 1,024-token prefix.
- Long-context extrapolation is a known failure case; the data is available in v0.1.0-data.
Results figure
Cite
@misc{mohith2026reloadorrecompute,
  author = {M, Mohith},
  title = {Reload or Recompute? A Calibrated Rule for KV-Cache Reuse Across Commodity GPUs},
  year = {2026},
  publisher = {Zenodo},
  doi = {10.5281/zenodo.24026972},
  version = {v0.1.2},
  url = {https://doi.org/10.5281/zenodo.24026972}
}